$0
Cloud API usage fees
For inference that runs entirely on your own hardware. Hardware, electricity, software licensing, and maintenance still have costs.
Plan for the full cost of ownership. Winn IndustriesAI hardware & systems architecture
Let’s talk
Independent consulting · Iowa City, Iowa
Hardware and model guidance for the work you need to do.
Practical AI hardware and systems architecture consulting, grounded in hands-on experience.
Let’s talk about your project Explore the work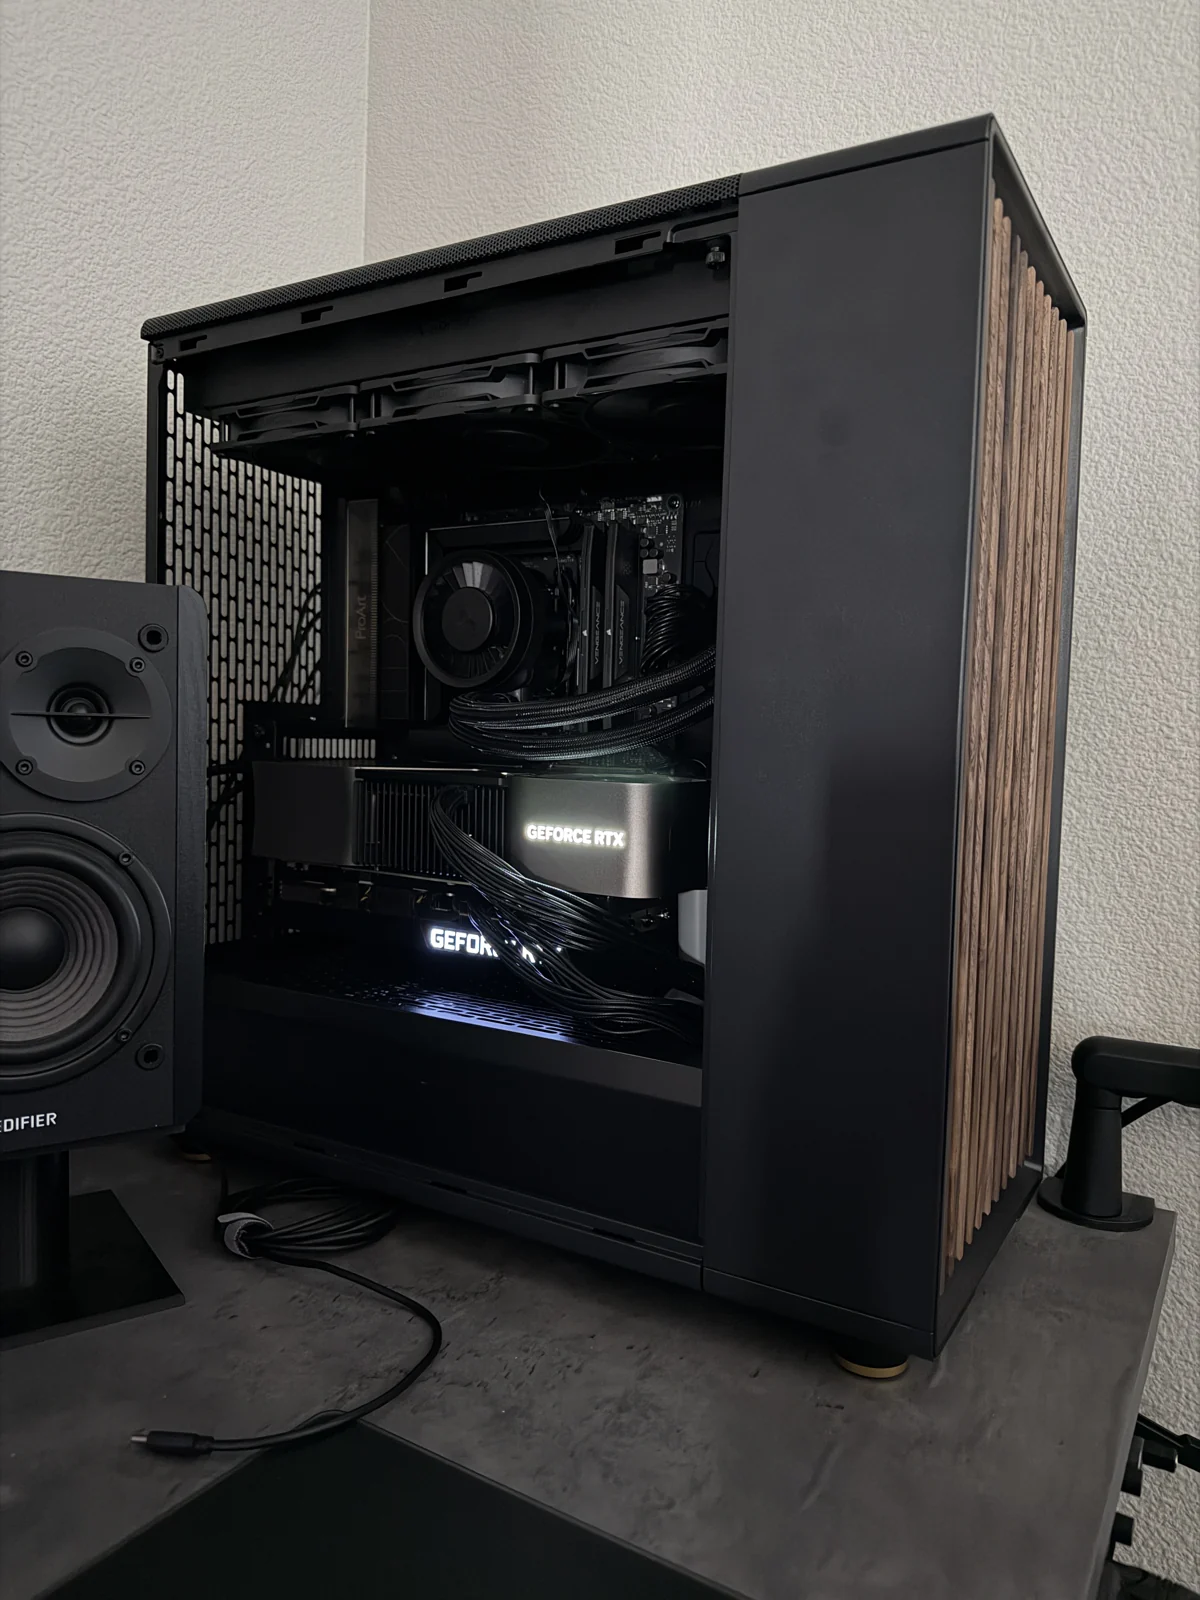
From the first hardware decision
to a system your team can use.
Hardware selectionLocal deploymentSystems architecture
Why local AI
Run suitable AI models on hardware you control. Keep local workflows close to your data, put compute to work across your team, and choose when a cloud service is worth using.
$0
For inference that runs entirely on your own hardware. Hardware, electricity, software licensing, and maintenance still have costs.
Plan for the full cost of ownership.75%
4-bit model weights use one quarter of the raw storage of 16-bit weights. That can make larger models practical on local hardware.
Theoretical weight storage only. Runtime overhead adds memory; quality needs testing.Offline
Downloaded models can run without an internet connection in a fully local workflow. Useful for working with documents and code on your own systems.
Downloads, updates, and connected services still need internet access.Technical background: LM Studio’s offline operation and Hugging Face’s quantization documentation. The storage comparison is 1 − (4 ÷ 16) = 75%; it is not a speed or total-memory benchmark.
Expertise
Server and GPU recommendations that account for model size, memory, bandwidth, power, and room to grow.
Guidance on local models and agent deployment for coding, document analysis, and everyday knowledge work.
Bring hardware and deployment decisions together in a practical plan for AI across your organization.
Local, cloud, or both
Local AI is compelling when control and repeat use matter. Cloud services can be a better fit for occasional demand or a model you cannot run locally. The right architecture can use both.
Winn Industries helps you evaluate model quality, memory, response time, and operating cost against the work you actually need to do. Local hosting alone does not guarantee security, compliance, or better performance. See Ollama’s local-only configuration guidance.
Discuss your AI workloadThe work
Built and tested with real hardware,
real models, and real constraints.
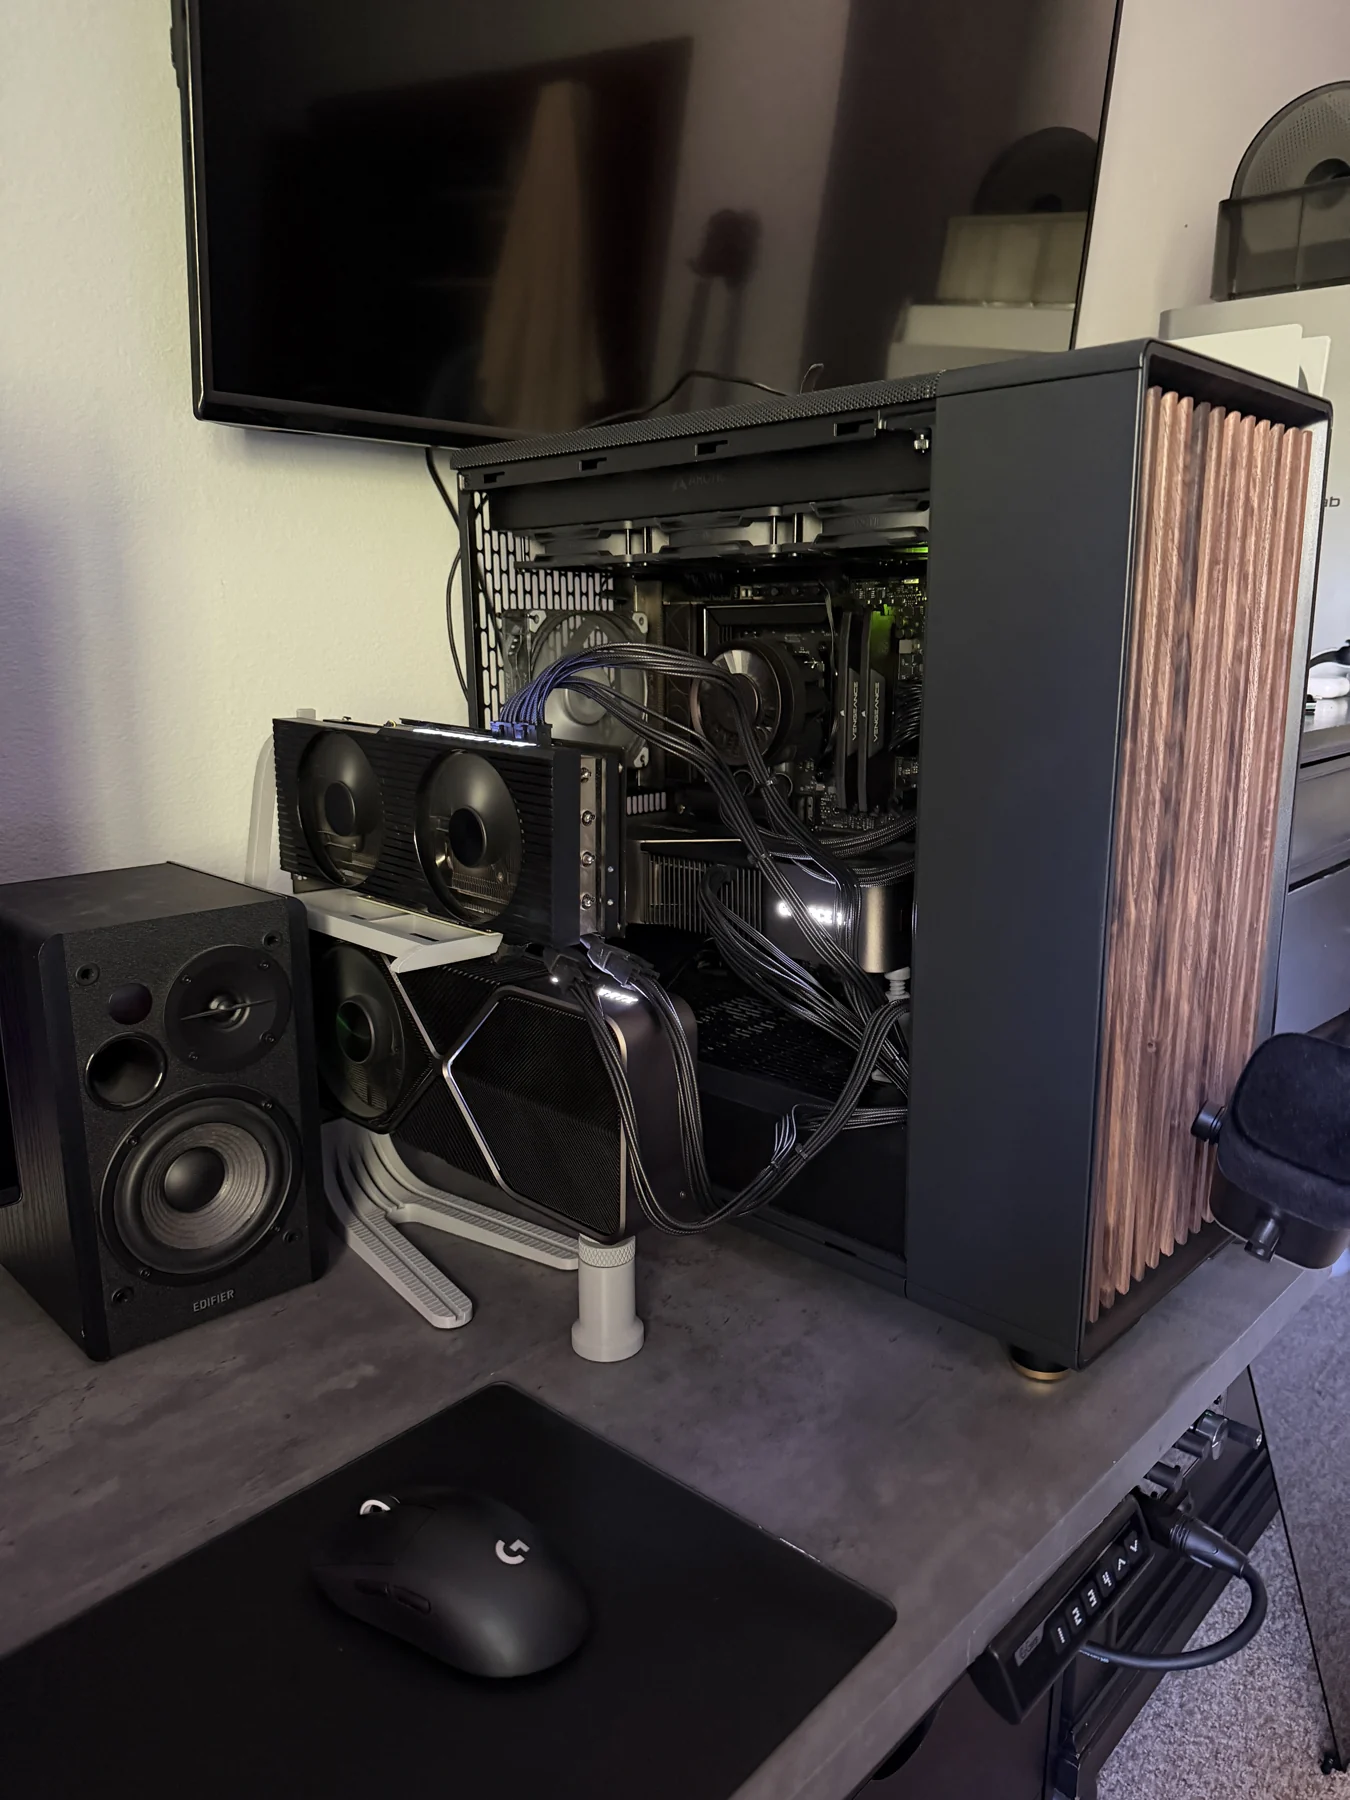
A hands-on build study
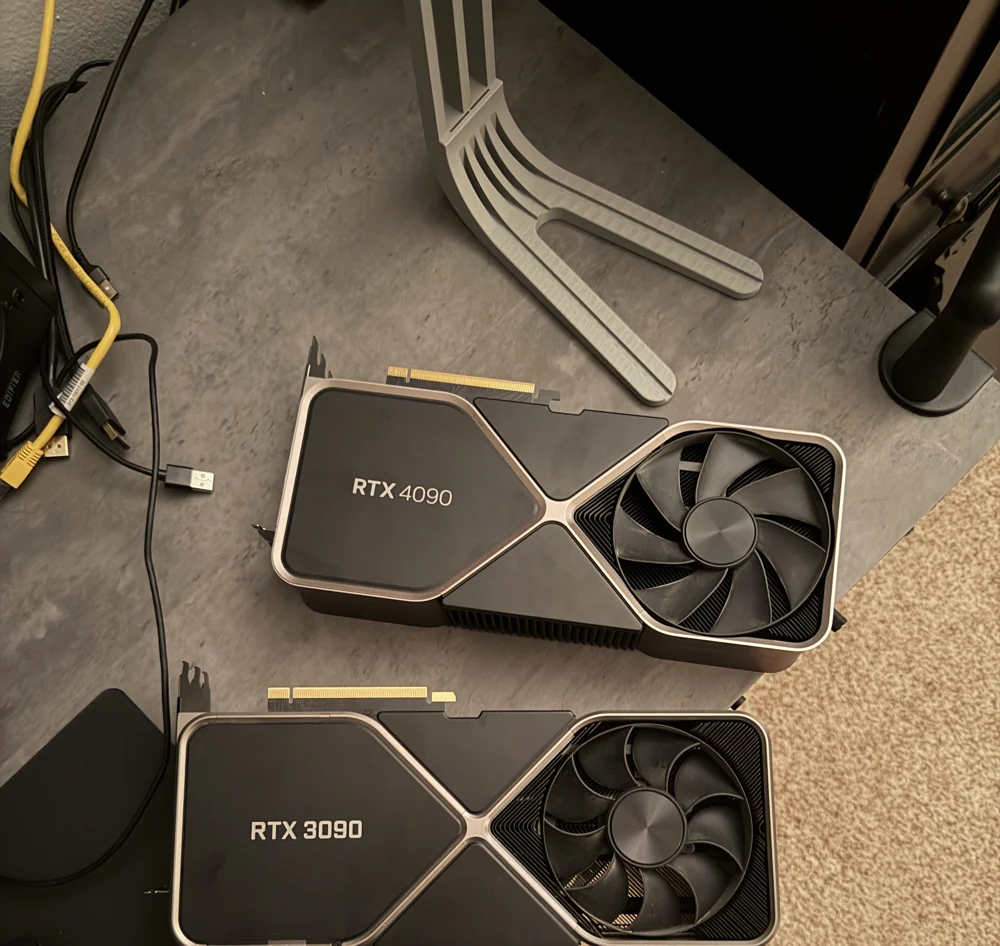
Moving from two GPUs to three expanded this local AI workstation to 72 GB of combined GPU memory. It also exposed a bottleneck: the bandwidth available to the third card.
That experience shapes my approach to consulting. Model size, memory, PCIe bandwidth, and power all need to work together.
The original RTX 4090 and RTX 3090 configuration offered 48 GB of combined VRAM, with both cards running at PCIe 4.0 ×8.
Adding another RTX 3090 allowed larger models to load, but the third card’s narrower ×4 connection reduced throughput in my testing. More capacity did not automatically mean a faster system.
The takeaway: select the whole platform around the workload. Combined physical GPU memory is a capacity figure; usable model capacity depends on the model and runtime.
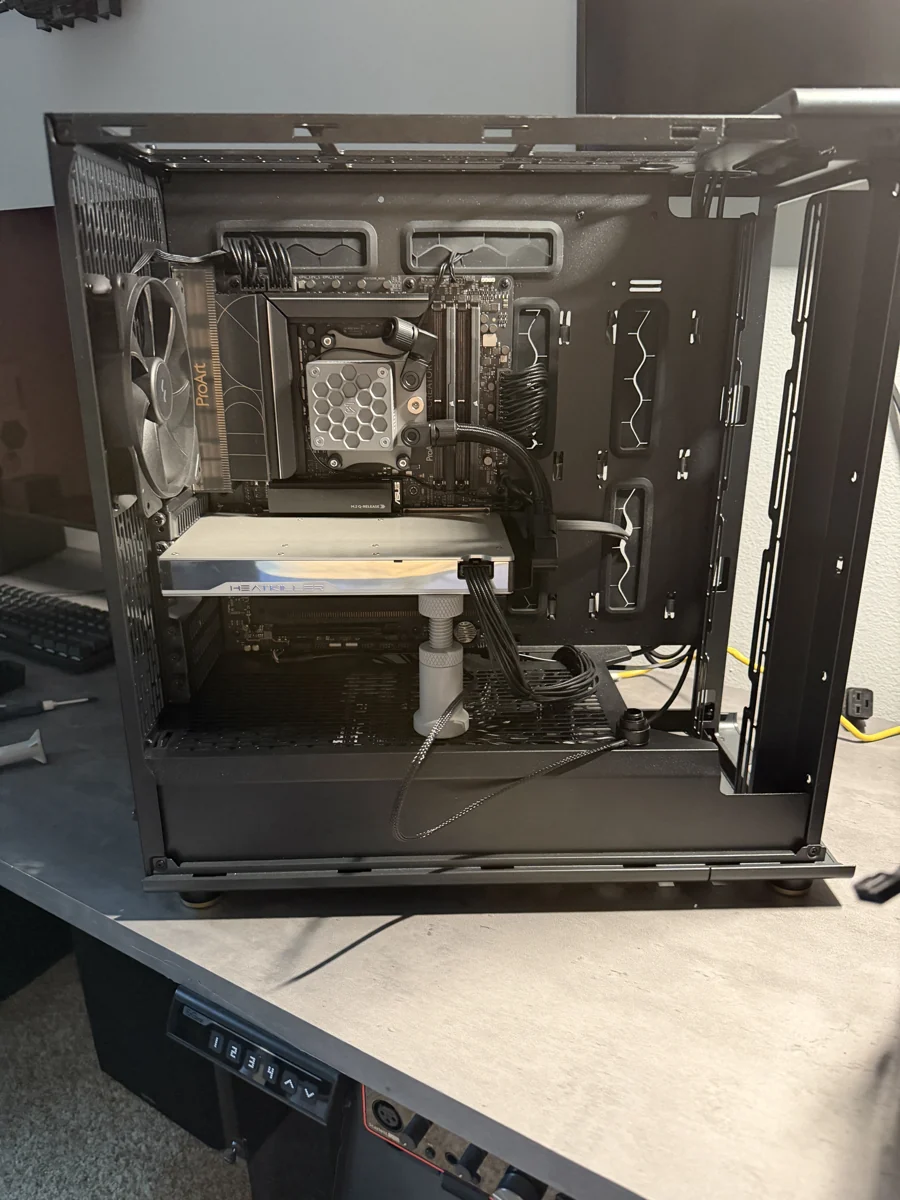
A practical perspective
Every component
is part of a
bigger system.
My experience spans dual- and triple-GPU builds, running a four-GPU RTX 3090 server, and working with a single RTX 5090.
Behind Winn Industries
Austin Winn
Winn Industries LLCI’m Austin Winn, an AI hardware and systems consultant based in Iowa City, Iowa.
I build and run local AI systems, test open models, and work through the hardware tradeoffs that shape real performance.
Through Winn Industries LLC, I help you choose hardware, deploy local models, and plan AI systems around the work your team needs to do.
Model families I’ve worked with
Coding, document analysis, and general reference. The right choice depends on your workload, available memory, and acceptable response time.
Let’s work together
Tell me what you want to run, what hardware you have,
and where you want to take it.
This link opens your email app. We use your message to respond to your inquiry. Please don’t send passwords or confidential records in an initial message. Read our privacy policy.